What Is JavaScript SEO?
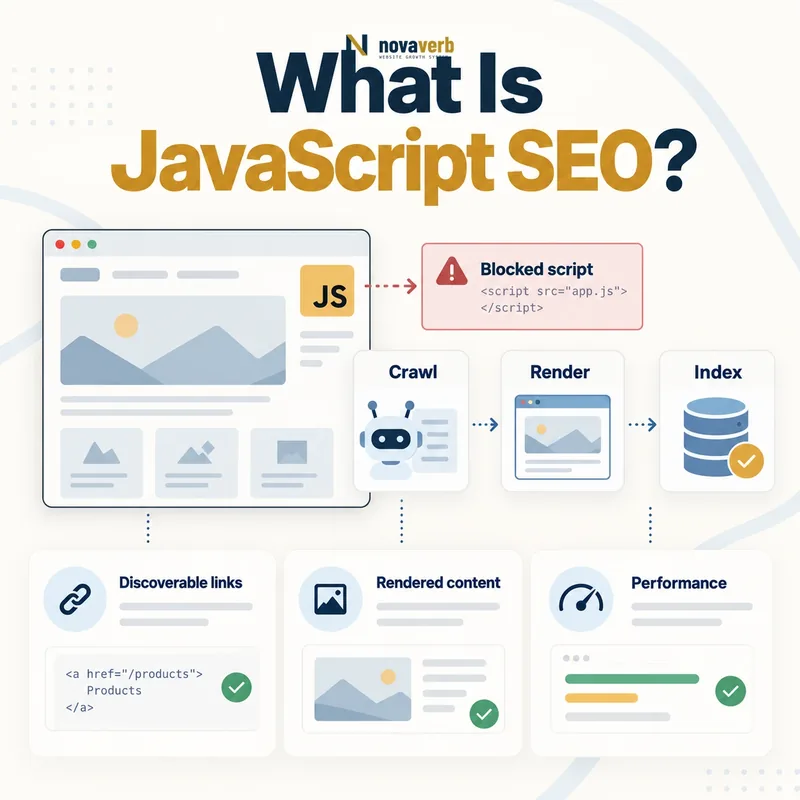
Modern sites use JavaScript for navigation, personalization, product interfaces, dashboards, filters and media. The language itself is not the problem. Risk appears when the initial response contains little useful information and the final page depends on scripts, APIs and application state that may fail or execute differently. A technical SEO audit must therefore inspect more than a screenshot. It compares the requested URL, HTTP response, raw HTML, fetched resources, rendered DOM and browser behavior. It also checks whether every meaningful destination has a stable address and whether internal links use ordinary anchor destinations. The goal is not to remove interactivity. It is to design a dependable content layer underneath it.
- Stable public URLs for meaningful views
- Useful initial HTML or reliable server rendering
- Accessible content after rendering
- Crawlable internal links with real href values
- Consistent titles, canonicals and robots signals
- Successful API and script dependencies
- Predictable behavior when JavaScript fails
- Frame the decision raised by What Is JavaScript SEO.
- Render the page with its required scripts and resources.
- Compare content, links, metadata and canonical signals.
- Trace each difference to the responsible template or script.
- Apply the fix and repeat both observations.
| Layer | Question | Evidence |
|---|---|---|
| URL | Does the view have an address? | Direct request |
| Response | What does the server return? | Status and headers |
| Raw HTML | What exists before scripts? | Page source |
| Resources | Which dependencies load? | Network log |
| Rendered DOM | What content finally exists? | DOM snapshot |
| Interaction | Can users and crawlers navigate? | Link and history tests |
JavaScript SEO succeeds when a modern interface keeps its public content and navigation reliable across every delivery layer.
How Do Crawling, Rendering and Indexing Differ?
A server may return a successful response while its body contains only an empty application shell. The crawler has technically fetched the URL, but meaningful content still depends on rendering. Rendering may then fail because a script is blocked, an API returns an error, hydration crashes or execution takes too long. Even a complete rendered page is not automatically selected for indexing; canonical, robots, duplication and quality decisions still apply. This separation prevents misleading diagnoses. A URL discovered in a crawl is not proof that all its content rendered. A rendered screenshot is not proof that internal links were crawlable. An indexed URL is not proof that the latest client state or metadata was processed. Record evidence at each stage.
- Confirm how the URL is discovered.
- Inspect its response status, headers and raw HTML.
- Record every required script and data request.
- Capture the rendered DOM after application work settles.
- Compare content, links and signals across states.
- Review the observed index outcome separately.
- Evidence for How Do Crawling, Rendering and Indexing Differ: the raw html returned by the server
- The rendered DOM after required scripts run
- Content, links and metadata that differ between those states
- Network, console and hydration failures tied to the page
- A repeatable test at the exact URL and device context
| Stage | Successful outcome | Common failure |
|---|---|---|
| Discovery | URL found through links or feeds | Route exists only after interaction |
| Crawl | Response and resources retrieved | Blocked or unstable request |
| Render | Meaningful DOM produced | Script or API failure |
| Signal extraction | Metadata and links understood | Conflicting client changes |
| Index evaluation | Eligible content assessed | Duplicate or low-value state |
| Retrieval | Page can match a query | Wrong intent or stale content |
Diagnose JavaScript pages stage by stage so a successful request or screenshot is never mistaken for complete search accessibility.
Server-Side Rendering vs Client-Side Rendering
Server-rendered HTML gives visitors and crawlers useful content before application code completes, but it still requires accurate caching, status codes and data handling. Client rendering can support highly interactive interfaces but creates more dependency on scripts, APIs and device execution. Static generation works well for stable public pages but needs a reliable refresh strategy when content changes. Hybrid systems can render public landing content on the server and hydrate interactive controls in the browser. The correct architecture follows content volatility, personalization, operational capacity and user needs. Marketing and indexable knowledge pages rarely benefit from being empty shells. Authenticated tools can prioritize application behavior because their public search requirements differ.
- Choose rendering by route purpose
- Deliver public landing content in initial HTML
- Keep personalized states out of canonical public output
- Define cache and regeneration behavior
- Preserve correct response codes across rendering modes
- Measure both server latency and client completion
- Frame the decision raised by Server-Side Rendering vs Client-Side Rendering.
- Render the page with its required scripts and resources.
- Compare content, links, metadata and canonical signals.
- Trace each difference to the responsible template or script.
- Apply the fix and repeat both observations.
| Strategy | Strength | Operational risk |
|---|---|---|
| Server-side rendering | Useful request-time HTML | Server cost and data latency |
| Client-side rendering | Rich application state | Empty shell and execution dependency |
| Static generation | Fast stable HTML | Stale output between builds |
| Incremental generation | Fast with controlled refresh | Complex invalidation |
| Hydrated hybrid | HTML plus interaction | Mismatch and duplicate work |
| Edge rendering | Location-aware response | Platform and cache complexity |
Rendering architecture should match the route’s public purpose while preserving truthful HTML, signals and response behavior.
What JavaScript SEO Problems Are Most Common?
Many failures originate in shared components, so one routing or rendering defect can affect thousands of pages. A button that changes views without an href may work for a person but provide no durable discovery edge. A route returning 200 for missing products can create soft-error behavior. Client code may replace a server canonical, duplicate a title or briefly expose default metadata. Consent logic can prevent essential content from loading, and API errors may leave skeletons indefinitely. Infinite scrolling and lazy loading add interaction-specific variants of the same principle: important content should not depend on an unproven event chain. Group findings by template, renderer, router and data dependency instead of treating each affected URL as an isolated edit.
- Initial HTML contains only an empty root element
- Navigation uses click handlers without real hrefs
- Missing routes return a branded 200 response
- Metadata differs between source and rendered DOM
- API failure leaves permanent skeleton content
- Hydration removes or duplicates server content
- Query and hash states create uncontrolled variants
- Frame the decision raised by What JavaScript SEO Problems Are Most Common.
- Render the page with its required scripts and resources.
- Compare content, links, metadata and canonical signals.
- Trace each difference to the responsible template or script.
- Apply the fix and repeat both observations.
| Defect | Evidence | Shared fix area |
|---|---|---|
| Empty shell | Raw HTML comparison | Rendering strategy |
| Button navigation | Anchor inventory | Link component |
| Soft 404 | Missing-route request | Router and server |
| Metadata conflict | Source versus DOM | Head manager |
| API-only content | Network failure test | Data and fallback |
| Hydration mismatch | Console and DOM | Server/client parity |
The highest-value fixes usually repair a shared rendering, routing or component rule rather than patching individual URLs.
How Should JavaScript Links and Routes Work?
A router can intercept a normal link, fetch route data and update the interface quickly. The same destination should still load correctly in a new tab, after refresh and when requested directly without prior application state. Buttons are appropriate for actions such as opening a modal, changing an in-page control or submitting data; they should not replace links to public pages. Hash fragments can identify sections within a document, but using them as the sole address for distinct content views can create ambiguity. Route parameters need normalization, and missing or unauthorized resources require honest status behavior. Verify breadcrumb, menu, card, pagination and faceted-navigation components because shared link abstractions often affect all of them.
- Assign a stable public URL to every indexable view.
- Render destinations as anchor elements with valid hrefs.
- Let the client router enhance rather than replace navigation.
- Test direct open, refresh and new-tab behavior.
- Preserve predictable back and forward navigation.
- Return accurate status codes for missing routes.
- Normalize equivalent parameter and trailing-slash forms.
- Evidence for How Should JavaScript Links and Routes Work: the raw html returned by the server
- The rendered DOM after required scripts run
- Content, links and metadata that differ between those states
- Network, console and hydration failures tied to the page
- A repeatable test at the exact URL and device context
| Behavior | Pass condition | Failure |
|---|---|---|
| Card destination | Real anchor href | Clickable div |
| Direct request | Complete route response | Application error |
| Refresh | Same meaningful view | State loss |
| New tab | Destination opens | Event-only navigation |
| Back button | Previous view restored | Loop or reset |
| Missing route | Honest error response | Branded status 200 |
Client-side navigation remains search-friendly when it accelerates ordinary web links instead of inventing a separate, session-dependent route system.
How Should Metadata and Canonicals Be Rendered?
Single-page applications often manage the document head during route changes. That process must update every relevant field, remove values from the previous route and produce the same result on direct entry. Server rendering should begin with route-specific metadata rather than a generic application title that is corrected later. Canonical URLs must reflect normalized public routes, not client-only state or the internal API address. Robots decisions should come from the content policy and must not disappear during hydration. If the application changes a canonical after initial delivery, compare which version appears in raw and rendered evidence. Structured data, when present, must describe visible current content and should not retain product, breadcrumb or article entities from the previous client route.
- Generate route-specific metadata on direct response
- Keep one canonical for the current public route
- Remove stale head elements during client navigation
- Align robots signals across server and client states
- Describe only visible current content
- Test repeated navigation between different page types
- Frame the decision raised by How Should Metadata and Canonicals Be Rendered.
- Render the page with its required scripts and resources.
- Compare content, links, metadata and canonical signals.
- Trace each difference to the responsible template or script.
- Apply the fix and repeat both observations.
| Element | Expected state | Common defect |
|---|---|---|
| Title | Unique current route | Default app name |
| Description | Matches landing intent | Previous route retained |
| Canonical | Normalized current URL | Duplicate or API URL |
| Robots | Policy remains consistent | Removed during hydration |
| Structured data | Current visible entity | Stale prior-route object |
| Social metadata | Current share state | Generic defaults |
JavaScript metadata is trustworthy only when direct requests and client transitions resolve to the same current, normalized page identity.
How Do Performance and Hydration Affect SEO?
Hydration attaches application behavior to server-rendered markup. If dates, randomized IDs, localization, authentication state or data versions differ, the client may warn, discard nodes or rebuild large parts of the page. That wastes work and can produce visual instability. Large script bundles compete for bandwidth and main-thread time, especially on mid-range mobile devices. Code splitting helps only when the route loads the chunks it actually needs without creating a long request chain. Third-party scripts, consent managers and experiments add more execution variance. Measure the initial HTML, content appearance, layout stability and interaction readiness on representative devices. Do not use a fast laboratory screenshot as proof that long tasks, hydration errors or late API dependencies are absent.
- Keep server and client data inputs consistent
- Avoid nondeterministic markup in hydrated regions
- Ship route-specific code instead of one oversized bundle
- Limit third-party execution before core content
- Reserve space for asynchronous components
- Record console, network and main-thread evidence
- Frame the decision raised by How Do Performance and Hydration Affect SEO.
- Render the page with its required scripts and resources.
- Compare content, links, metadata and canonical signals.
- Trace each difference to the responsible template or script.
- Apply the fix and repeat both observations.
| Symptom | Possible cause | Evidence |
|---|---|---|
| Content flashes | Client replaces server DOM | DOM recording |
| Duplicate nodes | Hydration mismatch | Console and snapshot |
| Late interaction | Heavy main-thread work | Performance profile |
| Blank component | Chunk or API failure | Network log |
| Layout shift | Async dimensions missing | Layout trace |
| Device variance | Bundle and CPU cost | Real-device test |
A rendered page is robust when server content remains stable and client code adds behavior without forcing visitors to pay for unnecessary reconstruction.
How Do You Audit JavaScript SEO?
Start with an inventory of frameworks, route types, rendering modes and shared components. Select public templates with different data sources and business importance. For each URL, record response codes, headers, raw HTML, script and API requests, rendered DOM, internal links, canonical, robots signals and visible content. Then disable or fail selected dependencies to see whether important meaning survives. Exercise direct entry, client navigation, refresh, new tab, back and forward behavior. Use an internal link audit to find destinations missing href paths, review orphan-page risks where relevant, and treat infinite scroll and lazy loading as focused component tests.
- Map frameworks, renderers, routers and public templates.
- Crawl raw responses with scripts disabled.
- Render the same representative URL set.
- Diff content, links, metadata and status meaning.
- Test direct requests and browser-history actions.
- Fail APIs, chunks and optional scripts deliberately.
- Reconcile discovered URLs with the content inventory.
- Group defects by shared component and retest fixes.
- Evidence for How Do You Audit JavaScript SEO: the raw html returned by the server
- The rendered DOM after required scripts run
- Content, links and metadata that differ between those states
- Network, console and hydration failures tied to the page
- A repeatable test at the exact URL and device context
| Check | Evidence | Pass condition |
|---|---|---|
| Initial HTML | Raw response | Core meaning available |
| Rendered DOM | Settled snapshot | Expected content present |
| Links | Anchor extraction | Valid public hrefs |
| Metadata | Source and DOM diff | Consistent current route |
| Routes | Direct and missing requests | Accurate behavior |
| Dependencies | Failure simulation | Graceful core content |
| Performance | Device profile | Timely stable rendering |
| Coverage | Inventory comparison | No hidden important URLs |
Start with a relevant free SEO check, continue the evidence workflow in Crawl Explorer, and review pricing when comparing continuous monitoring with a one-time manual review.
A complete JavaScript SEO audit proves route identity, content completeness and link discovery across both server delivery and client execution.