What Is Server-Side Rendering?
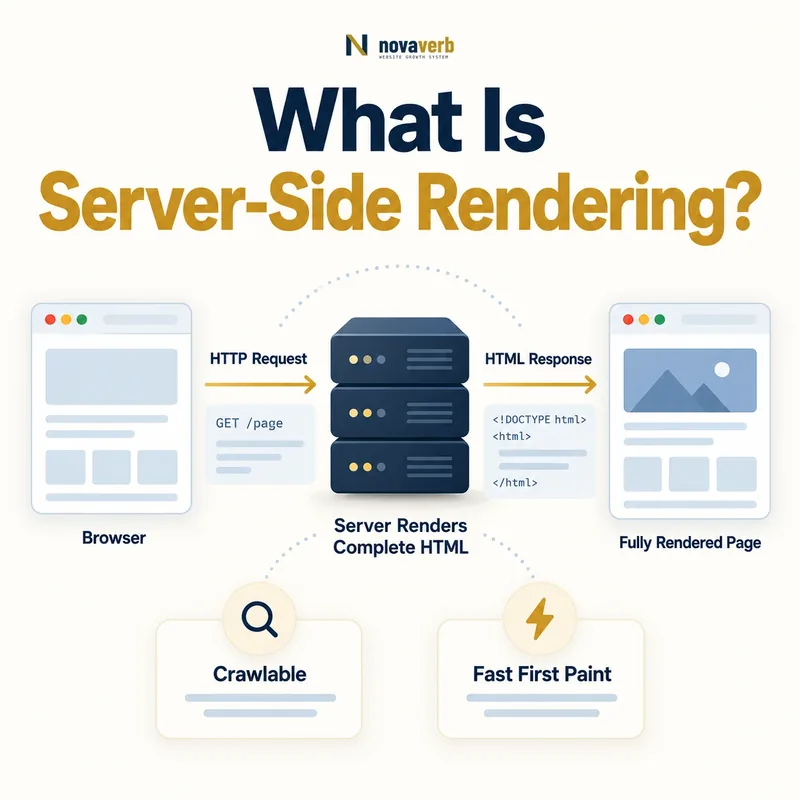
When a visitor requests a product, article or landing page, the server resolves the route, obtains required data, renders a document and returns it with an appropriate status and headers. The browser can display and parse that HTML before the application bundle finishes. Many SSR sites then hydrate the markup so menus, forms and application controls become interactive. SSR is a delivery strategy, not a guarantee of SEO quality. A rendered response can still contain the wrong canonical, a generic title, stale data, a soft error or no crawlable internal links. The value comes from making route-specific meaning available early and reducing dependence on client execution for public content.
- Request reaches a public route
- Server resolves content and status
- Template or framework creates HTML
- Response includes route-specific signals
- Browser displays the document
- Client code optionally hydrates interaction
- Later navigation may use application routing
- Frame the decision raised by What Is Server-Side Rendering.
- Render the page with its required scripts and resources.
- Compare content, links, metadata and canonical signals.
- Trace each difference to the responsible template or script.
- Apply the fix and repeat both observations.
| Stage | Responsibility | SEO evidence |
|---|---|---|
| Route match | Choose page handler | Stable URL |
| Data load | Fetch current content | Truthful page data |
| Render | Create meaningful HTML | Raw response |
| Response | Send status and headers | HTTP evidence |
| Display | Paint initial content | Visual timing |
| Hydration | Attach interactions | DOM and console |
SSR is useful when the server response carries the page’s core identity and content before optional browser enhancements begin.
How Does Server-Side Rendering Work?
The exact implementation varies by framework, but the lifecycle has common checkpoints. Route parameters must map to one normalized public URL. Data fetching needs timeouts and honest error handling. Templates must escape or structure content safely, and head elements must reflect the current entity. Cache layers may store the result to reduce repeated computation, which introduces freshness and invalidation decisions. During hydration, the client application expects its initial state to match the server markup. If prices, dates, experiments, locale or authentication differ, the browser can warn, replace nodes or show a flash of changed content. An audit should therefore follow the request through routing, data, template, caching and hydration instead of judging SSR from the final screenshot alone.
- Normalize and match the incoming route.
- Resolve permissions, locale and content identity.
- Fetch required data with bounded failure behavior.
- Render HTML, metadata and internal links.
- Return accurate status codes and cache headers.
- Initialize the browser with matching state.
- Hydrate only the interaction the route needs.
- Evidence for How Does Server-Side Rendering Work: the raw html returned by the server
- The rendered DOM after required scripts run
- Content, links and metadata that differ between those states
- Network, console and hydration failures tied to the page
- A repeatable test at the exact URL and device context
| Checkpoint | Pass condition | Failure |
|---|---|---|
| Routing | One route identity | Duplicate variants |
| Data | Current valid entity | Empty or stale payload |
| Template | Complete semantic HTML | Application shell |
| Head | Route-specific signals | Generic defaults |
| Cache | Fresh within policy | Stale page |
| Hydration | Server/client parity | Content replacement |
A dependable SSR lifecycle preserves the same page identity from route resolution through the hydrated browser state.
Server-Side Rendering vs Client-Side Rendering
SSR reduces the number of client steps required before public content appears, but it adds server computation and caching complexity. Client rendering can be appropriate for authenticated tools and highly personalized workspaces where public indexing is not the objective. Static generation produces HTML ahead of the request and can be faster for stable pages, while incremental approaches refresh selected output over time. The decision is not a contest between framework labels. It should reflect content volatility, request personalization, traffic, infrastructure and failure tolerance. Public category, product, location and editorial pages benefit from directly useful HTML. Private dashboards can prioritize application state and account security instead.
- Classify routes as public, private or mixed
- Measure content change frequency
- Define personalization boundaries
- Estimate server and cache requirements
- Specify fallback behavior for data failures
- Test representative mobile devices
- Frame the decision raised by Server-Side Rendering vs Client-Side Rendering.
- Render the page with its required scripts and resources.
- Compare content, links, metadata and canonical signals.
- Trace each difference to the responsible template or script.
- Apply the fix and repeat both observations.
| Model | Best fit | Main tradeoff |
|---|---|---|
| SSR | Dynamic public pages | Server and cache complexity |
| Client rendering | Private interactive apps | Execution dependency |
| Static generation | Stable public content | Rebuild freshness |
| Incremental generation | Large changing catalogs | Invalidation complexity |
| Hybrid rendering | Mixed route needs | More architecture decisions |
| Streaming SSR | Progressive server output | Boundary and testing complexity |
Choose rendering per route purpose so public search pages and private application views do not inherit each other’s unnecessary constraints.
What Are the SEO Benefits of SSR?
The largest benefit is evidence clarity. A crawler, browser or monitoring system can request a URL and immediately inspect the page’s main content and links. This reduces the chance that an API timeout or script error leaves an empty shell. Route-specific titles, canonicals and robots directives can be generated with the response rather than patched later. SSR may also improve the time until useful content appears, although real performance depends on server latency, cache hits, HTML size and hydration cost. The approach supports crawlability but does not create relevance, authority or helpful content automatically. Teams still need deliberate information architecture, internal linking and accurate copy.
- Core content present in raw HTML
- Internal anchors available before scripts run
- Route metadata visible on direct request
- Reduced dependency on rendering interactions
- Clearer monitoring and regression tests
- Potentially earlier meaningful display
- Frame the decision raised by What Are the SEO Benefits of SSR.
- Render the page with its required scripts and resources.
- Compare content, links, metadata and canonical signals.
- Trace each difference to the responsible template or script.
- Apply the fix and repeat both observations.
| Benefit | Evidence needed | Limit |
|---|---|---|
| Content access | Raw HTML contains meaning | Does not prove quality |
| Link discovery | Anchor extraction | Architecture still matters |
| Metadata stability | Head comparison | Values can still be wrong |
| Faster display | Real-device timing | Slow server can erase gain |
| Failure resilience | Script-disabled test | Data server may still fail |
| Monitoring clarity | Direct response assertions | Coverage must span templates |
SSR provides a stronger delivery foundation, but every claimed benefit should be verified against live responses and real route behavior.
What SEO Risks Can SSR Create?
A server-rendered branded error page that returns 200 can look polished while producing a soft error. A cache key that omits locale or currency can serve the wrong version to visitors. Personalized content accidentally included in shared cache output creates both trust and privacy problems. If the server and browser compute different markup, hydration may replace headings, prices or links. Route variants can each render complete pages even though only one should be canonical. SSR can also shift work from the browser to the origin and increase response time during traffic spikes. The correct response is not to abandon SSR but to define invariants for status, cache identity, content freshness, user state and client parity.
- Origin latency grows under uncached demand
- Shared caches mix locale or user state
- Deleted entities return a rendered 200 page
- Server and browser metadata disagree
- Hydration replaces meaningful markup
- Equivalent URLs each render independently
- Stale pages persist after content changes
- Frame the decision raised by What SEO Risks Can SSR Create.
- Render the page with its required scripts and resources.
- Compare content, links, metadata and canonical signals.
- Trace each difference to the responsible template or script.
- Apply the fix and repeat both observations.
| Risk | Evidence | Control |
|---|---|---|
| Slow response | Server timing | Cache and bounded data work |
| Stale output | Content comparison | Explicit invalidation |
| Soft error | Missing-route status | Honest response codes |
| Cache leak | Variant testing | Complete cache keys |
| Hydration mismatch | Console and DOM diff | Deterministic initial state |
| Duplicate routes | URL crawl | Normalization and redirects |
SSR remains safe when teams treat status, cache scope, freshness and hydration parity as testable production contracts.
How Do Hydration and SSR Work Together?
The server often serializes route data into the document so the browser can initialize without immediately fetching a different version. That data should contain only what the client needs and must not expose secrets or user-specific information through shared output. Deterministic rendering matters: timestamps, random identifiers, browser-only conditions and inconsistent locale formatting can change markup. Components that genuinely require browser information can defer that small region instead of making the entire page unstable. Partial or selective hydration can reduce shipped JavaScript, but it adds boundary decisions. Inspect the DOM before and after hydration, record console output and exercise slow devices where the unhydrated interval is visible longer.
- Serialize only safe route state required by the client.
- Use identical locale and formatting rules.
- Avoid random or time-dependent initial markup.
- Isolate browser-only components behind stable boundaries.
- Compare server HTML with the post-hydration DOM.
- Test slow execution and failed bundle states.
- Evidence for How Do Hydration and SSR Work Together: the raw html returned by the server
- The rendered DOM after required scripts run
- Content, links and metadata that differ between those states
- Network, console and hydration failures tied to the page
- A repeatable test at the exact URL and device context
| Input | Must match | Mismatch symptom |
|---|---|---|
| Content data | Same entity version | Text replacement |
| Locale | Same language and format | Date or number change |
| User state | Correct public boundary | Personalized flash |
| Identifiers | Deterministic values | Duplicate DOM |
| Route | Same normalized URL | Wrong head elements |
| Experiments | Stable assignment | Layout and copy swap |
Hydration should add behavior to stable server content, not renegotiate the page’s identity after it reaches the browser.
How Should SSR Caching and Status Codes Work?
Cache strategy determines whether SSR scales and whether its content stays trustworthy. Public pages may use shared caching when their output is identical for all visitors within the cache key. Personalized account pages require private behavior and should not leak through a shared layer. Locale, device variants, experiments and authentication must be considered explicitly rather than added accidentally. Content updates need a measured invalidation path, not an assumption that a short lifetime is always enough. Status meaning must survive every layer: a redirect should remain a redirect, a removed resource should not become a branded 200, and a backend failure should not be cached as a successful empty page. Review CDN, reverse proxy, framework and application decisions together.
- Document every output-changing cache dimension
- Separate public and personalized responses
- Define expiration and event-based invalidation
- Preserve redirect and missing-resource statuses
- Avoid caching transient failures as success
- Inspect headers at the public edge
- Frame the decision raised by How Should SSR Caching and Status Codes Work.
- Render the page with its required scripts and resources.
- Compare content, links, metadata and canonical signals.
- Trace each difference to the responsible template or script.
- Apply the fix and repeat both observations.
| Scenario | Expected behavior | Failure to avoid |
|---|---|---|
| Public stable page | Shared cache by full identity | Unnecessary origin render |
| Localized page | Locale-aware variant | Wrong-language response |
| Personalized view | Private or uncached | Shared user data |
| Content update | Timely invalidation | Stale product or article |
| Missing entity | Honest error status | Soft 404 |
| Temporary failure | Explicit failure behavior | Cached empty 200 |
An SSR response is trustworthy only when its cache identity, freshness and HTTP status all describe the same real page state.
How Do You Audit Server-Side Rendering?
Map route families, framework modes, cache layers and data sources before sampling URLs. Include successful, redirected, missing, localized, parameterized and recently updated examples. Record status, headers, response timing, raw content, metadata, internal links and serialized state. Then render the page and diff headings, body copy, anchors, canonicals and robots values after hydration. Repeat requests to observe cache behavior and vary only one identity input at a time. Simulate a slow or failed API and confirm that the page does not return confident empty content. Connect the work to the broader JavaScript SEO audit and use an internal link audit to confirm server-delivered anchors reach valid destinations.
- Inventory SSR routes, caches and data dependencies.
- Select normal, missing, redirected and variant URLs.
- Capture edge status, headers, timing and raw HTML.
- Render and diff the hydrated DOM.
- Test cache hits, invalidation and identity dimensions.
- Fail data and script dependencies deliberately.
- Reconcile visible values with authoritative content.
- Group defects by shared route or renderer.
- Evidence for How Do You Audit Server-Side Rendering: the raw html returned by the server
- The rendered DOM after required scripts run
- Content, links and metadata that differ between those states
- Network, console and hydration failures tied to the page
- A repeatable test at the exact URL and device context
| Check | Evidence | Pass condition |
|---|---|---|
| Initial content | Raw response | Core page meaning present |
| Status | Direct route request | Matches real resource |
| Metadata | Head extraction | Current normalized route |
| Links | Anchor inventory | Valid href destinations |
| Hydration | DOM diff | No harmful replacement |
| Cache | Repeated variant requests | Correct identity and freshness |
| Failure | Dependency simulation | Honest fallback |
| Performance | Edge and device timing | Acceptable complete response |
Start with a relevant free SEO check, continue the evidence workflow in Crawl Explorer, and review pricing when comparing continuous monitoring with a one-time manual review.
A complete SSR audit proves that the server response, cache and hydrated browser all represent the same accurate route.